Modern Enterprise Strategies Driving Scalable Data Engineering and Cloud Operations
Introduction
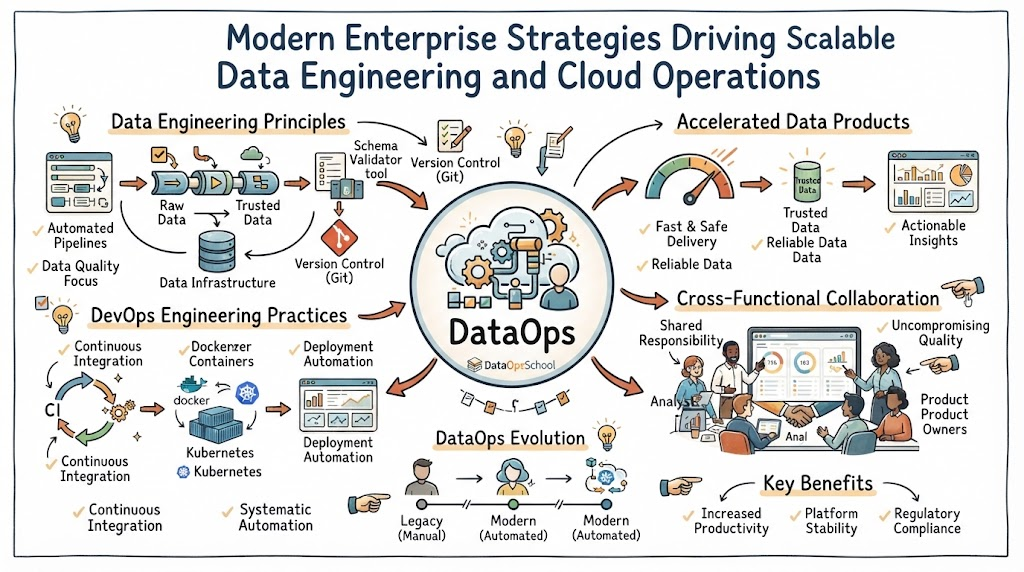
High-growth digital companies constantly ingest petabytes of disparate transactional, sensory, and behavioral inputs, yet broken workflows routinely degrade downstream analytics and disrupt executive operations. Forward-looking tech leaders recognize that manual scripts and isolated database patches fail to support high-velocity decision-making, which drives them to embrace DataOps to connect software engineering rigor directly with operational data lifecycles. Beginners asking what is DataOps discover a structured framework uniting cross-functional teams, continuous automation, strict quality controls, and resilient platform monitoring across hybrid clouds. Throughout this manual, engineers examine essential tool ecosystems, core courses, credential pathways, enterprise consulting options, and specialized services that resolve operational logjams. Dedicated educational resources like DataOpsSchool provide developers and architects with practical learning tracks, real-world scenario labs, and technical advisory programs to accelerate systemic operational maturity.
What Is DataOps?
DataOps unifies specialized software engineering principles, agile development patterns, continuous delivery automation, and pipeline observability to maintain production-grade analytical platforms. Instead of relying on ad-hoc maintenance routines, platform teams apply automated testing frameworks, strict configuration controls, and containerized staging sandboxes to validate transformations across cross-functional engineering, analytics, and infrastructure departments. Consider a fragile legacy pipeline where an operator manually updates SQL staging logic without testing upstream dependencies, immediately breaking executive reports when ingestion schemas shift without warning. In contrast, an automated system intercepts incoming payload modifications, spins up an isolated testing cluster, validates relational rules, checks boundary limits, and rejects erroneous inputs before tainted records reach primary storage layers.
Why DataOps Matters for Modern Data Teams
Dynamic cloud environments and surging ingestion volumes introduce persistent pipeline vulnerabilities, leaving manual administrative processes completely unable to sustain enterprise service level agreements. Unmonitored schema mutations and silent silent data corruption damage operational reliability, generate misleading dashboard metrics, compromise regulatory adherence, and erode executive confidence across all business units. Adopting automated operational standards remedies these production bottlenecks by inserting automated linting, schema validation, and pre-deployment testing into every continuous integration stage. This structured engineering discipline shields technical staff from endless emergency firefighting, cuts platform overhead expenses, guarantees rapid release velocities, and delivers fresh, verifiable metrics directly to enterprise decision engines.
How Does DataOps Work?
Production architectures operate as connected assembly lines that ingest, test, sanitize, orchestrate, deliver, and continuously measure raw information across distributed networks. Source collectors pull operational logs, routing them through containerized workers that execute initial schema assertions and structural checks before loading tables into centralized warehouses. Automated orchestration engines trigger modular transformation scripts, check relational constraints with dedicated validation engines, and deploy stable configurations through automated continuous delivery pipelines. Concurrently, native observability agents monitor ingestion lag, warehouse cluster utilization, query latencies, and unexpected column null-rates across every workflow. If anomaly detectors capture unexpected payload drops, automated circuit breakers halt pipeline execution, generate instant alerts for platform engineers, and isolate problematic datasets for systematic review.
DataOps Lifecycle
Coordinating dynamic enterprise platforms requires viewing operational workflows as an iterative cycle governed by standardized code, automated testing gates, and transparent platform metrics.
| Stage | What Happens | Example |
| Data Ingestion | Data enters the platform | API/database ingestion |
| Processing | Data is transformed | ETL/ELT |
| Testing | Data and pipelines are tested | Schema validation |
| Deployment | Changes are released | CI/CD |
| Monitoring | Pipeline health is tracked | Failure alerts |
| Governance | Data access and policies are managed | Access controls |
| Feedback | Issues and improvements are identified | Pipeline optimization |
Because cloud services evolve rapidly alongside changing consumer expectations, treating this entire journey as reproducible software ensures that engineers introduce updates safely while protecting platform stability.
Key Principles of DataOps
Operational discipline requires engineers to write version-controlled transformation scripts, automate continuous deployment checks, establish absolute staging parity, and enforce automated quality validations across all platform layers. Technical teams isolate local development environments within dynamic containers, require peer code reviews on git pull requests, and enforce automated schema tests before merging new code into primary branches. Uniting database administrators, pipeline developers, platform engineers, and business analysts dismantles legacy silos that historic handoffs created. Prioritizing automated regression tests and real-time observability enables systems to isolate data mutations early, maintain stringent compliance mandates, and deliver reliable business intelligence to operational teams daily.
DataOps Tools
Rather than searching for a mythical all-in-one software package, engineering departments combine modular, purpose-built technologies that excel across distinct automation, orchestration, storage, and validation layers.
| DataOps Function | Example Tools/Technologies | Purpose |
| Version Control | Git | Track changes |
| CI/CD | Jenkins, GitHub Actions, GitLab CI | Automate delivery |
| Orchestration | Apache Airflow | Manage workflows |
| Transformation | dbt | Transform data |
| Containers | Docker, Kubernetes | Standardize environments |
| Data Quality | Great Expectations | Validate data |
| Observability | Data observability platforms | Monitor data health |
| Cloud Data | AWS, Azure, Google Cloud | Data infrastructure |
| Monitoring | Prometheus, Grafana | Monitor systems |
| Databases | PostgreSQL, MySQL, cloud databases | Store data |
Engineering leaders select specific tools after analyzing corporate infrastructure, pipeline throughput, internal skill proficiencies, security boundaries, cloud provider limitations, and immediate business milestones.
DataOps vs DevOps vs Data Engineering
While these interconnected engineering disciplines share automation principles and delivery concepts, each domain focuses on fundamentally different technical responsibilities within modern technology teams.
| Area | DataOps | DevOps | Data Engineering |
| Main Focus | Reliable data operations | Reliable software delivery | Building data systems |
| Automation | Data workflows | Software infrastructure | Data pipelines |
| Testing | Data + pipeline quality | Application/infrastructure testing | Data transformation testing |
| Monitoring | Data and pipeline health | Applications/infrastructure | Pipeline/system health |
| CI/CD | Data workflows | Software deployments | Pipeline deployments |
These domains reinforce one another when platform operations teams manage cloud infrastructure, data engineers develop core ingestion and transformation algorithms, and operational specialists construct end-to-end testing, delivery automation, and proactive monitoring architectures across analytical warehouses.
Benefits of Implementing DataOps
Embracing automated operational architectures improves developer productivity, reduces platform debugging hours, eliminates pipeline interruptions, and guarantees dependable data accuracy for analytical products. Replacing manual deployment rituals with automated delivery checks catches structural schema defects before bad rows infect production warehouses or executive dashboards. Standardized continuous integration patterns allow developers to design, test, and release complex transformation logic rapidly without threatening overall system reliability. These practices yield predictable delivery cadences, reinforce corporate security compliance, minimize platform support overhead, and foster collaborative problem-solving across engineering departments.
Real-Life DataOps Scenarios and Industry Experience
A multi-region e-commerce company suffered recurring weekend dashboard failures whenever third-party logistics vendors altered API response schemas, abruptly halting internal business reporting until engineers spent days rewriting manual extraction code. The team solved this vulnerability by introducing automated pull-request validation pipelines that enforce rigid schema expectations, which automatically quarantined malformed records without halting the wider pipeline. Another logistics firm facing massive overnight processing backlogs decoupled its brittle monolith into containerized, event-driven transformation tasks coordinated by modern workflow orchestrators, reducing runtimes from hours to minutes while gathering granular telemetry. Adopting automated validation suites, isolated sandbox environments, and real-time observability transformed both organizations into nimble, resilient engineering powerhouses.
How to Implement DataOps in an Organization
Engineering leadership launches an operational transformation by cataloging existing database assets, recording every manual operational intervention, auditing historical pipeline failures, and identifying severe system bottlenecks across current extraction flows. Teams then define quantitative data health indicators focusing on freshness, row completeness, referential integrity, and schema compliance, while migrating all transformation scripts, infrastructure definitions, and environment variables into a centralized repository. Next, developers embed automated unit tests and schema assertion gates into continuous integration runners, verifying that incoming updates deploy safely through staging sandboxes directly into production without human delay. Finally, teams configure end-to-end data lineage tracing, granular performance monitors, role-based access policies, and continuous review forums to continually optimize pipeline reliability as workloads expand.
DataOps Training and DataOps Course
Ambitious technical professionals elevate their technical value by completing structured DataOps Training programs and hands-on courses that connect software engineering patterns directly to complex data infrastructure. A comprehensive DataOps Course focuses on real-world engineering simulations, automated pipeline deployment, declarative orchestration engines, schema assertion testing, and production monitoring rather than purely conceptual presentations. Enrolling in specialized platforms such as DataOpsSchool allows infrastructure operators, database engineers, and analytics specialists to master modern operational principles through guided tutorials and technical labs. Learning these integrated skills arms practitioners with the automation capabilities, problem-solving skills, and architectural knowledge needed to maintain robust data platform ecosystems.
DataOps Certification
Securing a professional DataOps Certification formally validates an engineer’s capability to architect automated pipelines, manage complex orchestrators, implement continuous testing, and design comprehensive observability platforms. Industry-recognized credentials evaluate practical implementation expertise, requiring candidates to resolve live production bugs, configure delivery pipelines, and enforce automated governance standards. Preparing for these rigorous exams forces practitioners to expand their technical command of automated testing, containerized workloads, and cloud storage systems while closing architectural gaps. Combining verifiable enterprise production achievements with formal credentials signals exceptional competence to technical recruiters and executive leadership teams evaluating platform candidates.
Certified DataOps Engineer
A Certified DataOps Engineer builds, automates, tests, and monitors enterprise-grade data platforms to ensure consistent data delivery across distributed architectures. These specialists exhibit advanced knowledge of container orchestration, declarative pipeline scheduling, continuous integration tools, statistical anomaly detection, and real-world system telemetry within cloud environments. Software engineers, pipeline builders, and analytics practitioners wanting to transition into high-impact operational roles unlock significant career opportunities along this engineering path. Educational ecosystems like DataOpsSchool provide structured roadmaps, comprehensive courses, and practical technical labs designed to help candidates prepare for and clear rigorous professional engineering credentials.
Certified DataOps Architect
At an enterprise leadership level, a Certified DataOps Architect blueprints scalable cloud foundations, formulates global automation strategies, and enforces ironclad data governance, compliance, and cybersecurity architectures. While deployment engineers concentrate on individual pipeline scripts and validation jobs, architects select modular platform tooling, plan cross-region disaster recovery operations, define platform-wide access controls, and guide organizational operational roadmaps. Professionals commanding this expertise bridge the technical gap between business stakeholders, analytical specialists, and cloud infrastructure engineers, preventing technical debt accumulation across the enterprise. Securing this senior credential requires years of hands-on platform construction, deep proficiency with cloud networks, and a proven talent for guiding organizational operational transformation.
DataOps Tutorial: Where Should Beginners Start?
Novice practitioners must construct a firm technical base by mastering relational databases, cloud storage concepts, the Linux command line, shell automation, and Git version control systems. Once comfortable navigating foundational tools, beginners should assemble basic extraction scripts, gradually introducing declarative workflow schedulers to manage task execution orders and handle retry dependencies. After configuring basic transformations, learners must incorporate automated data validation frameworks into their repositories, establishing continuous integration actions that reject invalid code updates automatically. As their competence expands, students should build operational observability dashboards, monitor platform alerts, complete complex portfolio projects, and pursue professional credentials to validate their operational capabilities.
DataOps Consulting and DataOps Services
Enterprises battling recurring data downtime, brittle pipeline scripts, sluggish deployment cycles, and sprawling architectural stacks frequently partner with experienced DataOps Consulting teams to rebuild their operational foundations. Professional DataOps Services audit existing pipeline weaknesses, implement automated deployment workflows, construct automated data quality gates, and deploy end-to-end observability tools tailored to business needs. Furthermore, external platform experts advise leadership during intricate cloud platform transitions, assisting teams in enforcing standardized access policies, optimizing compute expenditures, and eliminating platform vulnerabilities. Platforms like DataOpsSchool unite advanced educational curricula with experienced consulting teams, empowering growing organizations to deploy automated, scalable, and highly available analytical operations.
Common Mistakes to Avoid in DataOps
Many engineering groups waste resources purchasing modern software licenses while ignoring cultural silos, undocumented pipeline ownership, manual communication bottlenecks, and fractured team dynamics. Another frequent mistake involves treating data workflows exactly like static software builds, failing to anticipate that dynamic, uncontrollable upstream inputs require dedicated runtime validation checks. Teams also invite operational failures when they fail to track configuration files, schema updates, and transformation logic inside centralized version-control repositories. Finally, technology departments regularly damage their operational agility by committing these avoidable implementation errors:
- Omitting automated data lineage tracking, which severely complicates root-cause investigations during sudden pipeline interruptions.
- Postponing data validation until records land in presentation tables, allowing erroneous numbers to distort executive reports.
- Forcing human sign-offs for routine production deployments, which creates severe operational friction and stalls team momentum.
- Disregarding strict access controls and continuous compliance auditing, leaving sensitive organizational records open to regulatory violations.
- Neglecting automated incident tracking loops, which prevents engineers from refining pipeline architectures after production defects occur.
How to Choose the Right DataOps Approach
Determining a winning operational strategy demands a realistic appraisal of data volume, infrastructure complexity, regulatory requirements, technical proficiencies, and existing cloud architectures across the company. Agile organizations managing standard analytical workloads thrive with managed, low-maintenance orchestration services paired with declarative transformation tools requiring minimal dedicated infrastructure administration. Conversely, multi-national enterprises navigating strict healthcare or banking compliance, hybrid data centers, and high-velocity streaming inputs require containerized architectures, distributed compute engines, and robust enterprise observability platforms. Engineering leaders must select modular, open-standard technologies that immediately eliminate existing operational bottlenecks while providing ample technical flexibility to absorb future business expansion.
Who Should Learn DataOps?
Because operational maturity transforms enterprise productivity, mastering modern data operations accelerates career advancement for practitioners across numerous technology domains:
- Data Engineers: Builders wanting to automate repetitive pipeline tasks, reduce daily firefighting, and release transformation code safely through continuous delivery frameworks.
- DevOps Engineers and SREs: Systems professionals looking to adapt their infrastructure automation, observability, and platform reliability skillsets to complex analytical architectures.
- Analytics Engineers and Data Scientists: Analytics practitioners needing predictable, high-quality data feeds and isolated staging sandboxes to deploy reliable predictive models.
- Cloud and Platform Engineers: Infrastructure professionals focused on provisioning resilient compute clusters, managing distributed storage, and reducing cloud spending.
- Technical Managers and Architects: Leaders charged with bridging cross-departmental silos, enforcing automated governance protocols, and accelerating production delivery cadences.
Acquiring these sought-after operational capabilities allows technical specialists to translate their past software and database experiences into modern, high-impact platform leadership roles.
Why DataOpsSchool Can Be a Useful Resource
Mastering distributed platform engineering requires access to clear, production-tested training programs and practical technical instruction. DataOpsSchool delivers an educational platform committed to training technology specialists in data engineering excellence, cloud platform stability, continuous integration automation, and platform observability. Through its extensive DataOps Tutorial series, hands-on DataOps Training tracks, and comprehensive DataOps Course materials, students gain the production competencies required to earn certifications like Certified DataOps Engineer and Certified DataOps Architect. Moreover, the platform delivers specialized DataOps Consulting and DataOps Services to modern enterprises, helping engineering departments construct scalable, observable, automated data platforms that drive consistent business value.
Frequently Asked Questions
1. What is the fundamental difference between DataOps and DevOps?
DevOps automates application code testing, containerized packaging, and infrastructure provisioning to maintain software platform uptime. DataOps adapts these delivery concepts to analytical architectures, orchestrating operational pipeline code alongside dynamic, volatile data payloads to guarantee absolute analytical correctness.
2. Can an organization practice DataOps using only open-source tools?
Organizations can assemble a dependable operational ecosystem using open-source utilities like Git for version control, Apache Airflow for scheduling, dbt for model building, and Great Expectations for quality assertion, provided their engineers possess the skills to configure and maintain this infrastructure.
3. How does implementing automated testing improve data reliability?
Automated testing checks incoming records against specific schema constraints, null boundaries, and numeric ranges before processing jobs execute. Stopping tainted inputs at ingestion boundaries protects production databases from corrupt records, saving engineers countless hours of emergency debugging and preserving analytical reporting integrity.
4. Is DataOps relevant only for large enterprise organizations?
Growing technology teams profit immensely from these operational practices because automated testing, version control, and continuous integration eliminate manual maintenance work, allowing small engineering groups to support complex analytics platforms without drastically increasing headcount.
5. Which programming languages are most important for DataOps practitioners?
Python and SQL represent the bedrock programming skills for modern operational engineering. Developers leverage Python to construct custom integration connectors, orchestrate tasks, and build automated testing suites, while SQL provides the universal engine for transforming, querying, and verifying relational datasets.
6. How does DataOps accelerate regulatory and governance compliance?
Tracking comprehensive data lineage, standardizing security access rules, and versioning every transformation script produces an unalterable operational audit trail. This transparency enables platform teams to demonstrate compliance with privacy regulations without conducting grueling manual operational audits.
7. Does adopting DataOps require rebuilding all existing pipelines from scratch?
Engineering teams introduce operational principles incrementally by first migrating scattered transformation scripts into a shared Git repository. Next, operators add basic schema tests and execution monitors to critical pipelines, steadily modernizing aging infrastructure without disrupting live analytical systems.
8. What role does data observability play in daily platform operations?
Observability tooling tracks data health by continuously monitoring pipeline latencies, record counts, schema drift, lineage mappings, and execution anomalies. It notifies engineers of unexpected behavioral shifts instantly, empowering teams to remediate pipeline faults before downstream consumers spot broken charts.
9. Can DataOps help reduce overall cloud infrastructure expenses?
Continuous monitoring exposes idle compute clusters, redundant transformation jobs, failed task retries, and inefficient queries across cloud data warehouses. By streamlining orchestration schedules, purging stale staging tables, and right-sizing compute instances, platform engineers eliminate significant cloud waste.
10. How do workflow orchestration tools fit into this framework?
Orchestration platforms organize task dependencies, handle schedule execution, and supervise pipeline operations across distributed infrastructure. They confirm that transformations launch only after upstream ingestion tasks succeed, managing automated retries and dispatching notifications whenever an operational stage encounters issues.
11. What is the best way to introduce automated deployments safely?
Engineers construct automated continuous integration pipelines that run schema validations, unit tests, and integration assertions inside isolated staging environments. Transformation code merges into production environments only after passing all automated test suites, preventing unverified modifications from destabilizing production workloads.
12. Why are practical labs critical when preparing for engineering certifications?
Certifications measure your skill in diagnosing live system faults, building continuous integration workflows, and scheduling complex workloads. Reading conceptual guides cannot replicate operational reality, making interactive hands-on labs vital for developing the deep troubleshooting intuition that production systems require.
Conclusion
Building modern, high-velocity data platforms demands moving beyond ad-hoc operational fixes by embracing an engineering culture rooted in end-to-end automation, continuous verification, deep observability, and cross-functional team collaboration. Growing enterprises face mounting operational complexities across distributed cloud environments, making disciplined platform practices essential to protect analytical pipelines from silent corruption and expensive downtime. Technical teams achieve this reliability by executing a structured modernization roadmap: placing transformation code under version control, inserting automated testing gates at every ingestion boundary, and continuously tracking platform telemetry. Technology professionals can fast-track their career development by completing hands-on courses, studying detailed technical tutorials, and achieving industry-recognized engineering certifications that validate their operational mastery. Dedicated platforms like DataOpsSchool actively support this professional evolution by delivering structured training curricula, rigorous certification prep, and specialized consulting services designed to modernize enterprise architectures. Lasting operational success comes from mastering reliable deployment practices, safeguarding data quality, and continually optimizing pipelines to deliver dependable enterprise intelligence.
Leave a Reply