Key Metrics That Modern Engineering Teams Use to Maintain Total Cloud Uptime
Introduction
People tap phone screens and expect digital banking tools or gaming servers to respond instantly. Broken code, flooded networks, or fried data drives can suddenly bring business operations to a halt. Site Reliability Engineering combines standard software coding tasks with daily infrastructure maintenance to protect digital systems. Smart engineers build defensive shields around production software so outages never shock normal everyday users. SRESchool.com serves as a specialized knowledge center where curious tech workers and enterprise teams learn these vital practices. Learners discover how to safeguard live platforms through interactive lessons, guided practice labs, and seasoned industry advice.
What Is SRESchool.com?
Picture an auto mechanic who invents self-tightening bolts so car engines never rattle apart on bumpy roads. Site Reliability Engineering works the same way by using custom code to defend big computer clusters. Teams measure application health, track small delays, and build scripts that resolve repeating glitches without human touch. When unexpected software crashes occur, engineers avoid personal blame and instead fix the deeper technical causes. This ongoing habit of tracking, automating, and learning keeps web services rock solid as customer numbers climb.
Why Does SRESchool.com Matter?
Enterprises rely on complicated mixtures of cloud nodes, transaction databases, web interfaces, and network cables. A single dropped connection or faulty database query can lock out thousands of eager buyers instantly. Frustrated customers then close the broken store, spread negative reviews, and buy from someone else instead. SRE teams use sensitive telemetry indicators to catch creeping memory leaks before customers face broken shopping carts. Making reliability an everyday engineering duty safeguards company income, protects public reputations, and eliminates frantic weekend incident firefighting.
What Does an SRESchool.com Team Do?
A reliability engineer tracks live incoming traffic, cpu heat, and database query latency on big screens. Smart paging systems wake up assigned responders the moment an error rate crosses a critical threshold. The engineer follows prebuilt incident playbooks, rolls back flawed changes, and restores normal service for active customers. Next, the team writes background automation code so machines handle that exact problem alone next time. They also review historical server usage to purchase extra computing power before major product release days. Afterward, the group writes a calm postmortem document to identify structural fixes and prevent similar platform crashes.
Key SRE Terms Made Easy
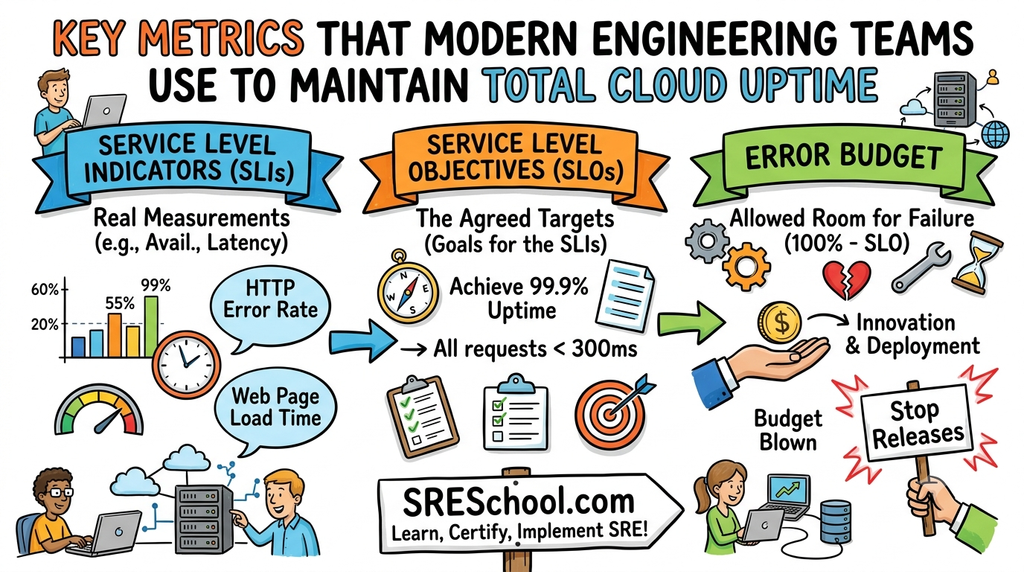
Engineers rely on short operational words to evaluate system stamina and make informed delivery decisions. A Service Level Indicator measures raw operational performance, such as network latency or successful page loads. A Service Level Objective represents the official target percentage that the engineering team commits to hitting. An Error Budget calculates the exact slice of downtime a team can burn before freezing new feature releases. Operational toil represents boring, repetitive computer chores that a basic shell script could finish instead. Observability allows engineers to diagnose mysterious software failures by collecting system metrics, error logs, and request traces.
| SRE Term | Simple Meaning | Example |
| SLI | A direct measurement of current service speed or reliability. | Tracking the percentage of checkout calls that finish within two seconds. |
| SLO | The formal performance target promised to your users. | Keeping website uptime above ninety-nine point nine percent each quarter. |
| Error Budget | The safe amount of room for unexpected downtime. | Having twenty-one minutes of permitted system disruption across an entire month. |
| Toil | Repetitive manual maintenance tasks that lack enduring value. | Copying database backup files between different test servers by hand every morning. |
| Observability | The ability to understand internal software states using outside signals. | Reading distributed request traces to pinpoint the exact microservice causing slow lookups. |
| On-Call | An active shift where an engineer responds to alerts. | Carrying an emergency laptop over the weekend to triage critical system panics. |
| Incident | An unexpected system breakdown that degrades normal business functions. | A database failure that prevents online customers from viewing their shopping baskets. |
What Is SRE Training?
Aspiring engineers enter SRE Training programs to master core infrastructure design and production operations skills. Beginners explore foundational system health metrics, craft bash automations, and configure realistic Service Level Objectives. They study techniques for balancing error budgets, reading system logs, and leading calm blameless postmortem discussions. Cloud labs allow students to troubleshoot broken container clusters inside safe practice environments without harming live users. SRESchool.com delivers hands-on educational pathways that help professionals wipe away tedious manual maintenance through intelligent automation. These real-world exercises give technicians the practical confidence needed to tame unexpected enterprise infrastructure crises.
What Is SRE Certification?
A recognized SRE Certification signals to technology recruiters that a candidate understands modern cloud reliability standards. A Certified Site Reliability Engineer proves ability in tracking system performance, mitigating outages, and designing automated self-healing scripts. Formal training programs offer clear learning milestones that cover observability frameworks, distributed networks, and incident triage methods. Yet passing a test is merely the foundation of an engineer’s broader professional career path. True mastery requires coupling exam knowledge with actual troubleshooting on messy, unstable production servers. Great engineers showcase their skill through successful production fixes rather than test scores alone.
What Is a Site Reliability Engineering Course?
An effective Site Reliability Engineering Course walks students along a logical, step-by-step path toward operational mastery. Beginners start with basic Linux terminal commands before configuring telemetry agents and drafting Service Level Objectives. Afterward, students simulate live outages, build self-healing scripts, and control containerized cloud systems at scale. Students explore an exhaustive SRE Tutorial collection to review difficult architectural ideas through straightforward analogies. This practical approach assists junior coders, seasoned developers, and system administrators as they elevate their production skills. Tackling realistic incident simulations prepares technicians to handle real enterprise computing pressures with steady competence.
SRE Tools Made Simple
Engineers configure specialized SRE Tools to track system vitals, expose bugs, and resolve application failures quickly. Programs such as Prometheus scrape performance metrics like processor usage, available disk storage, and network packet rates. Dashboards built on Grafana display these data points as intuitive, real-time charts that highlight strange performance anomalies. Distributed tracing frameworks like OpenTelemetry follow single user clicks across complex networks of internal services. Automation software deploys updated code containers, replaces failing nodes, and scales server clusters automatically. Combining these powerful tools allows engineers to resolve hidden bottlenecks before external users experience any disruption.
| Learning Area | What Learners Can Practice |
| Metrics Collection | Configuring Prometheus to monitor memory consumption across cloud instances. |
| Visual Dashboards | Designing clear Grafana panels to visualize current transaction speeds. |
| Distributed Tracing | Instrumenting web code with OpenTelemetry to track slow database queries. |
| Automated Recovery | Crafting Python scripts that restart crashed background workers automatically. |
| Infrastructure as Code | Deploying identical, throwaway testing environments using simple software blueprints. |
Real-Life Scenarios and Experiences
- An unexpected viral video directs massive crowds of new shoppers to a boutique clothing site. Auto-scaling rules detect the rapid CPU spike and spin up fifteen fresh cloud instances within minutes. The storefront continues processing orders cleanly without freezing customer screens or dropping connection requests.
- A developer deploys a flawed database migration that slows down mobile banking account lookups. Latency metrics climb past the agreed Service Level Objective threshold and trigger an immediate high-priority alarm. The responder instantly reverts the deployment, restores sub-second lookup speeds, and preserves the team’s error budget.
- A technician wastes two hours every afternoon manually restarting memory-heavy analytics workers on several servers. The worker writes a simple daemon script that checks process memory and restarts bloated tasks automatically. This quick automation eliminates boring operational toil and returns ten hours of productive time every week.
- A severe lightning strike takes down an entire regional data center without any advance warning. Smart routing layers recognize the dead region and divert incoming traffic to an alternate operational site. Users experience no service interruption while platform engineers assess the storm damage safely from afar.
What Is SRE Consulting?
Enterprises often engage SRE Consulting advisors to evaluate their computing setups and identify fragile system dependencies. External specialists audit alert configurations, inspect continuous integration pipelines, and help department heads define sensible reliability targets. They teach internal teams how to replace manual administrative chores with modern cloud automation workflows. Advisors also coach staff to run productive, blame-free postmortem meetings that identify true operational flaws. Partnering with a reliability consultant enables companies to scale digital infrastructure quickly while dodging catastrophic architecture errors.
What Is SRE as a Service?
Fast-growing organizations without internal operations units contract SRE as a Service to gain round-the-clock infrastructure protection. Outside reliability specialists handle production monitoring, configure incident alerting policies, and step in during critical outages. These engineers optimize telemetry displays, run disaster recovery exercises, and guarantee cloud capacity expands smoothly with customer traffic. However, business owners must outline exact operational requirements before signing agreements with an external provider. Clear boundaries ensure outside specialists protect system uptime without hindering internal developers from launching new features.
What Is Corporate SRE Training?
Forward-thinking technology departments choose Corporate SRE Training to unite developers, quality analysts, and operations personnel under shared practices. When every engineer speaks the same operational language, teams build durable, crash-resistant software right from the beginning. Instructors adapt curriculum labs to mirror the enterprise’s specific cloud architectures, tool pipelines, and internal security guidelines. Teams run simulated incident drills together so everyone stays calm and coordinated during real production disruptions. Sponsoring collective technical education tears down operational barriers, shrinks mean time to recovery, and guarantees stable business software.
Common Mistakes to Avoid When Choosing Reliability Programs
- Enrolling in theoretical courses that lean on text slides while skipping hands-on terminal command sessions.
- Prioritizing multiple-choice test preparation over actual hands-on programming and infrastructure automation practice.
- Studying legacy, physical server setups rather than modern containerized workflows and distributed cloud ecosystems.
- Registering for generic training that never demonstrates how error budgets influence daily code deployment decisions.
- Trusting instructors who lack proven experience managing real, high-traffic consumer systems through severe outages.
- Selecting educational programs that completely ignore incident management drills, alert routing, and postmortem documentation.
- Believing a wall certificate guarantees employment without assembling a portfolio of functioning automation projects.
- Committing to rigid training curricula that do not let engineering teams experiment with their own operational tools.
How SRESchool.com Can Help
SRESchool.com functions as an international training and consulting resource for engineers pursuing modern reliability excellence. Students can join an intensive Site Reliability Engineering Course to build relevant, hands-on production skills. The educational center provides structured study paths for technicians seeking to earn their Certified Site Reliability Engineer credential. Organizations can schedule customized Corporate SRE Training to upskill their development and infrastructure teams together. Businesses can also retain seasoned advisors through professional consulting and managed reliability offerings to reinforce complex cloud environments. By offering rich documentation and practical guides, the platform equips every technologist to design dependable, highly scalable platforms.
Frequently Asked Questions
1. What is Site Reliability Engineering?
Engineers use programming logic to solve traditional system administration, scaling, and computer networking problems. This operational philosophy replaces manual tasks with automated scripts and enforces explicit reliability targets for web services. Teams spend their working hours preventing software outages rather than running around fixing things by hand. The practice balances the need for rapid software updates with the customer requirement for rock-solid stability.
2. Do I need coding skills to learn SRE?
Knowledge of fundamental coding logic helps immensely because reliability engineers write automation programs and read application code every day. Most engineers rely on straightforward languages like Python, Go, or Bash to build monitoring agents and infrastructure tools. You do not need to build full web applications, but you must write scripts that parse logs and control servers. Practical courses can teach you the core scripting techniques needed for daily operations work.
3. What is the difference between DevOps and SRE?
DevOps represents an organizational culture that promotes close communication and shared responsibility between developers and operations staff. Site Reliability Engineering delivers the practical handbook, daily rituals, and technical measurements needed to realize those cultural ideals. DevOps directs teams to break down silos, while SRE defines metrics like SLOs to track success. Both concepts work together to help software organizations ship reliable updates quickly and safely.
4. What is an error budget?
Error budgets represent the exact amount of acceptable downtime or system imperfection a digital product can sustain each month. The value is simply one hundred percent minus your service’s official Service Level Objective target. An objective of ninety-nine percent leaves a one percent error budget for the current calendar period. Teams burn this allowance to release experimental features, launch big updates, or absorb unexpected hardware failures.
5. What does operational toil mean?
Toil describes repetitive, manual engineering tasks that provide no long-term improvement to the overall software architecture. These recurring duties scale directly with system growth, solve no fundamental problems, and waste valuable engineering talent. Examples include manually updating configuration files on individual servers or periodically purging temporary log caches. SRE engineers eliminate these boring chores through automated scripts, freeing up time to build better platform features.
6. How long does it take to learn SRE?
Dedicated beginners usually gain a dependable grasp of fundamental reliability concepts within three to six months of study. Prior experience with Linux server administration, computer networking, or general software programming speeds up your progress considerably. Mastering distributed platform designs, enterprise incident triage, and deep system telemetry requires several years of hands-on production experience. Consistent daily practice with virtual cloud labs helps learners master these complex operational skills much faster.
7. Why are postmortems important in SRE?
Teams write a formal postmortem report after resolving a critical system outage or unexpected software crash. The document details the timeline of events, explains the technical failure, and outlines steps to prevent future recurrences. SRE practitioners maintain a blameless culture that studies fragile system designs rather than targeting individual human errors. This supportive learning mindset guarantees that discovered operational defects lead to permanent technological defenses across the enterprise.
8. What are the best tools to learn first?
Aspiring engineers should begin by mastering fundamental Linux terminal operations, bash scripting, and Git version control systems. Next, pick up Prometheus to collect system health metrics and Grafana to build responsive visual monitoring dashboards. Learning container engines like Docker and orchestration systems like Kubernetes is also vital for modern cloud engineering roles. Practicing with these standard technologies provides the core skills required to operate enterprise software reliably.
9. Can small startups use SRE practices?
Founders can adopt fundamental reliability principles early without hiring a dedicated reliability specialist for the team. Early-stage startups should establish basic uptime objectives, automate their deployment pipelines, and configure central error alerts immediately. Building strong operational habits early protects developers from accumulating crippling technical debt as the user base expands. Thoughtful reliability planning ensures that your digital platform scales gracefully alongside incoming customer traffic.
10. How does SRE improve system security?
Reliability practices boost application security by keeping all server environments uniform, patched, and continuously monitored through automation. Automated deployment pipelines allow engineers to push emergency security patches across hundreds of servers without costly manual errors. Comprehensive telemetry sensors flag unexpected network connections or unusual CPU spikes before malicious attackers do widespread damage. A dependable, well-architected infrastructure network presents fewer loose components and fragile cracks for hackers to exploit.
11. What is an on-call rotation?
Engineering teams run on-call rotations so someone is always awake and ready to handle critical production alerts. When automated monitoring systems detect an active outage at midnight, the paging tool alerts the scheduled technician. The engineer logs in, follows established recovery playbooks, fixes the broken component, and informs the business. Fair rotation schedules protect user service uptime while preventing individual engineers from experiencing excessive stress and burnout.
12. Is an SRE certificate enough to get hired?
Earning a formal certification displays your personal dedication, but employers also evaluate your actual hands-on troubleshooting capabilities. You should build personal homelab projects, automate cloud resources with code, and document your experiments in public repositories. Demonstrating how you diagnose broken services and design resilient architectures gives recruiters confidence in your technical skills. Blending formal study certificates with a strong portfolio of practical automation code creates an attractive engineering resume.
Conclusion
Modern technology organizations rely on Site Reliability Engineering to keep their cloud infrastructure, mobile applications, and databases operating cleanly. The discipline balances aggressive product releases with platform stability through clear metrics, automated scripts, and blameless retrospective reviews. Professionals can acquire these skills by following structured tutorials, building hands-on labs, and pursuing industry certifications. Meanwhile, established enterprises can utilize team training and external consulting to harden their mission-critical computing environments. SRESchool.com provides the educational tracks, hands-on practice modules, and professional insights required to master distributed platform operations. Adopting reliability methods today ensures your digital services remain stable, scalable, and prepared for future growth.
Leave a Reply